



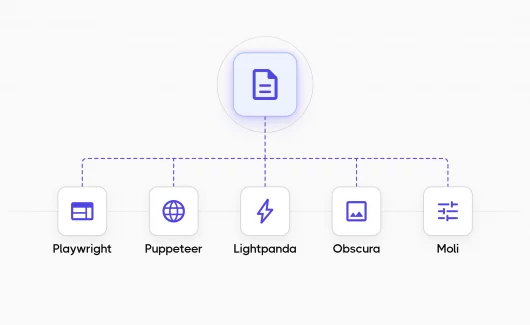
Playwright is a browser automation framework. It drives Chromium, Firefox, and WebKit to test how applications behave in real browser engines. That makes it a strong default for E2E testing. The problem appears as the suite grows. More scenarios mean more page loads, browser interactions, and time waiting for CI. AI coding agents can generate additional tests quickly. Running those tests still costs browser time, even when they repeat similar workflows with different inputs. Before adding more workers, consider the browser each worker runs. Does every validation case need a full rendering engine? Obscura, Lightpanda, and Moli offer a different way to speed up functional tests: run them in lighter browsers. They are alternatives to the browser underneath your automation, rather than competing test runners. This article compares that approach with Playwright-driven Chromium.
Why Playwright Alternatives Change The Browser and Keep The Test Framework
Moving from one automation library to another leaves much of the execution cost unchanged if both launch Chromium. A headless browser still performs layout and rendering work. Hiding its window does not turn it into an HTML parser. Lightweight engines reconsider that work. They execute page JavaScript, maintain a DOM, and make network requests. Some skip painting entirely. Others provide their own rendering pipeline or enable it only when needed. All three browsers discussed here expose the Chrome DevTools Protocol (CDP). Automation tools can use that protocol to control them. Sharing a protocol does not guarantee identical browser behavior or support for every automation API. There are cheaper fixes to try first:
- Remove fixed sleeps.
- Remove duplicate scenarios.
- Remove unnecessary UI setup.
- Narrow overly broad navigation waits.
An agent-generated test with a long sleep still sleeps in a smaller browser. A slow backend remains slow too. Once browser execution is a meaningful bottleneck, these engines become interesting.
Obscura: A Lightweight Alternative To Playwright’s Chromium That Renders Pages
Obscura is an open-source headless browser written in Rust. It executes JavaScript through V8 and includes its own rendering engine. It does not require Chromium. Its distinguishing feature is rendered output with a smaller browser footprint. Obscura supports screenshots, screencasting, and PDF output. For testing, screenshots offer useful context when an assertion fails. You can inspect the page instead of reconstructing it entirely from DOM snapshots.
Obscura is worth evaluating when diagnostic images are part of your workflow. Its recorded memory use was close to the non-rendering alternatives in the comparison below. Its total execution time was higher. The trade-off is browser fidelity. Its renderer is independent of Chromium, Firefox, and WebKit. A screenshot from Obscura can explain an Obscura failure; it cannot establish that Chrome renders your application correctly.
Evaluate Obscura when you want lightweight functional execution with screenshots. Grab a binary release and check custom controls and rendering-sensitive interactions against your full-browser baseline.
Lightpanda: A Playwright Alternative That Skips The Rendering Pipeline
Lightpanda is an open-source browser built from scratch in Zig. It uses V8 for JavaScript execution. Its browser APIs and DOM implementation are its own, rather than Chromium’s. Lightpanda prioritizes workflows that need page state rather than pixels. Your application can execute scripts and update the DOM without producing a normally rendered page. That makes it a candidate for large sets of input variations and state assertions. This design also changes failure investigation. Expect to rely on assertion errors, HTML, and accessibility snapshots rather than ordinary page screenshots. Upstream advertises text-only PNG and PDF dumps, but those are different from screenshots of a rendered application.
Before moving a large regression group, check these points:
- Web Platform coverage. Sharing V8 with Chrome does not provide Chrome’s complete Web Platform implementation. Check the browser APIs your application uses.
- Platforms. Lightpanda distributes Linux and macOS binaries; Windows users need WSL.
- License. It uses AGPL-3.0 licensing, so review the terms for your deployment.
Evaluate Lightpanda when fast DOM-oriented feedback is the priority. Keep visual and layout-dependent requirements in a full-browser job.
Moli: An Alternative To Playwright With Rendering As An Explicit Choice
Moli is an open-source headless browser written in Rust. It combines V8 with Servo’s Stylo for CSS computation. It is a standalone browser kernel, not a Chromium wrapper. Its distinguishing feature is optional layout and rendering. The default mode avoids real layout and painting. Enabling --layout adds geometry and screenshot capabilities. Its architecture performs visual work on demand instead of continuously maintaining rendered state.
That gives engineers a choice within one engine:
- Use the lighter mode for repeated functional checks.
- Enable layout when a diagnostic image or real element dimensions are needed.
The recorded comparison includes both modes, so the cost of that choice is visible. Rich-text editing is another reason to evaluate Moli separately from Lightpanda. The integration coverage discussed in the linked article includes TinyMCE inline and Trix input in default mode. That is a useful compatibility signal, not a guarantee for every editor or configuration. Default-mode geometry is a placeholder. Enabling layout does not turn Moli into Chrome. Also distinguish engine capabilities from the input behavior your automation adapter actually uses.
Evaluate Moli when you want a fast default with an optional rendered mode. Install the latest release and compare both modes against the interactions your application requires.
What The Recorded Test Runs Show For Playwright Alternatives
A recorded comparison ran a shared 21-test suite against TodoMVC. Scenarios create, edit, filter, complete, and delete todos. Input variations include long text, umlauts, and HTML-like content. The measurements below are medians across three runs per configuration, recorded on October 14–15, 2026. Wall time includes command startup, browser launch, execution, and shutdown.
| Recorded configuration | Wall time | Relative speed | Peak browser memory | Rendered screenshots captured |
|---|---|---|---|---|
| Playwright / Chromium | 64.2 s | 1× | 3,081 MiB | Yes |
| Obscura | 34.8 s | 1.8× | 86 MiB | Yes |
| Lightpanda | 10.2 s | 6.3× | 73 MiB | No |
| Moli default | 10.8 s | 5.9× | 92 MiB | No |
| Moli layout | 29.2 s | 2.2× | 113 MiB | Yes |
All configurations recorded 19 passes and the same two failures:
- One test called missing custom steps.
- Another expected persistence across refresh from an application that stored todos only in memory.
Those failures were retained for reporting demonstrations. These are recorded results, not a fresh run for this article.
This compares configured test jobs, not isolated browser-engine performance. The setups differed in several ways:
- Playwright recorded video and traces.
- Playwright waited for
networkidleafter navigation; the alternative integrations used different navigation waits. - The app was remote.
- Moli ran a day later, with a newer integration build.
Those differences contribute to the gap. An optimized Playwright job would need a separate measurement. The figures do not establish a universal speedup or a ranking across applications.
The useful result is narrower: this small functional suite produced matching outcomes with substantially lighter browser processes. The runner still consumed memory too. Measure whole-job resource use before choosing a CI worker count.
Which Tests Should Move To Alternatives To Playwright First?
Choose scenarios by what their assertions prove. A validation message or saved record is a different requirement from a reachable button or correctly positioned modal.
| Requirement | Suggested execution path |
|---|---|
| Required fields, invalid values, boundary inputs | Trial group for a lightweight engine |
| CRUD flows, filtering, DOM-based state assertions | Trial group after comparing outcomes |
| Screenshot context for a functional failure | Obscura or Moli layout, after compatibility checks |
| Overlays, hover behavior, drag-and-drop, pointer targeting | Full-browser coverage |
| Visual regression and responsive layout | Target browser engines |
| Chrome, Firefox, or Safari compatibility | Corresponding full-browser coverage |
Input semantics deserve attention. The lightweight integrations used in this comparison dispatched synthetic clicks directly to selected elements. A synthetic click can reach a button that an overlay blocks for a person. Rendered screenshots do not change that fact.
For tests written by agents, review the assertions before celebrating a faster run. A test that only checks for text may miss a failed save. Speed does not repair an assertion that proves too little. To move tests safely:
- Start with a small group.
- Run it in both the candidate engine and your existing browser.
- Investigate outcome differences before expanding.
- Pin engine versions, align waits and artifact policies, and measure startup, execution, and memory separately.
- Keep periodic full-browser execution of the migrated group. Rerunning only lightweight failures in Chromium cannot catch false greens.
Keep Failures Inspectable
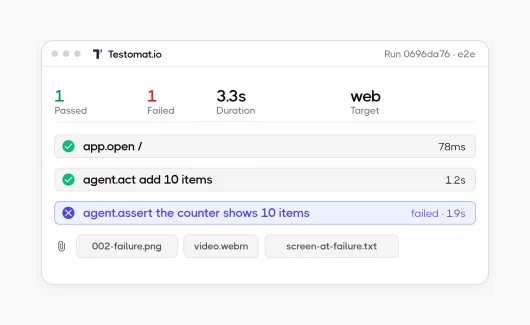
You can connect the Testomat.io reporter to your test runner to inspect failures in a shared report. It reports results and supports logs and artifact uploads. With artifact storage configured, a failed test can carry:
- Screenshots.
- Videos.
- Traces.
- Other attached evidence.
Results from every engine appear in a shared CI/CD dashboard, and flaky-test detection shows whether a scenario behaves differently across engines.
You need to collect the evidence the selected engine provides. A non-rendering run can retain:
- HTML snapshots.
- Accessibility snapshots.
It cannot supply a normal page screenshot. You need to keep engine and mode information in the run metadata so investigators know which execution produced the failure.
Bottom Line: Use Playwright Alternatives Alongside Playwright
Move repeated functional checks before moving browser-fidelity requirements. The strongest candidates are scenarios whose value comes from application state rather than rendering. Keep Playwright for cross-browser coverage and interactions that depend on how a person reaches a control.
All three engines can be used in the CodeceptJS testing framework through its Obscura, Lightpanda, and Moli helpers. The shared I.* API lets compatible scenarios run through different browser configurations. See the CodeceptJS tutorial for how such a framework is organized.
A CodeceptJS test does not specify an engine:
I.amOnPage('/dashboard');
I.click('Analytics', '.widgets');
I.see('Analytics', 'h1');
I.seeElement('.analytics-widget .chart-bar');
The same CodeceptJS test can run in Playwright, Puppeteer, Lightpanda, Obscura, or Moli. With CodeceptJS as the test framework, you can split test runs between the most effective browser engines.
Existing Playwright Test projects therefore need a compatibility layer. Adapt the browser setup through a custom fixture. That fixture can connect over CDP instead of launching bundled Chromium. Compatible tests and page objects can then remain in the Playwright ecosystem. Plan explicitly for:
- Server lifecycle.
- Per-test contexts.
- Storage cleanup.
- Worker isolation.
Moli and Lightpanda also support WebDriver, which lets you run tests written with the WebdriverIO framework.
A few final points on adopting alternative browser engines:
- Start with a separate job and a small selection of existing tests.
- Keep the normal Chromium project as the baseline.
- The timings above came from a shared-adapter comparison, not a direct Playwright Test migration benchmark. No direct Playwright compatibility run was performed for this article.
When you divide test runs between engines, you can send results from each job to the Testomat.io reporter. Failures from Chromium and from lightweight browsers appear in a shared report. Add the engine name to the run metadata so you can see which browser produced each failure. You can try Testomat.io for free or log in to your account to connect the reporter to your first multi-engine run.